
Scale up is the atomic unit of AI data center infrastructure. In the scale-up domain, dozens to hundreds of accelerators are connected inside a single rack so directly that the whole rack appears to AI software as one logical XPU—a single compute domain. Inside that rack, the goal is to connect as many processors as possible in a full any-to-any configuration, where every processor can talk directly to every other one.
Today, the connectivity inside that rack uses copper as the medium to carry data. Copper is reliable, inexpensive, low-latency, and draws little power. As models grow, the scale-up domain is spreading from one rack to several—rack scale to row scale. Copper can't reach that far, because for every bandwidth doubling, the distance copper can carry it is divided roughly in two. Crossing racks forces two changes at once: the longer links go optical, and a switching layer is required, because thousands of XPUs can't each be wired directly to all the others. Marvell builds the silicon for both—the interconnect and the switching—across every link inside a scale-up domain, copper and optical, on whichever protocol an operator prefers.
Here's how three macro-level distance domains compare: scale up makes many accelerators act as one domain. Scale out ties many of those domains into a cluster, and scale across connects clusters in separate data centers. The scale-up domain comprises —the highest-bandwidth, lowest-latency connections in the data center.
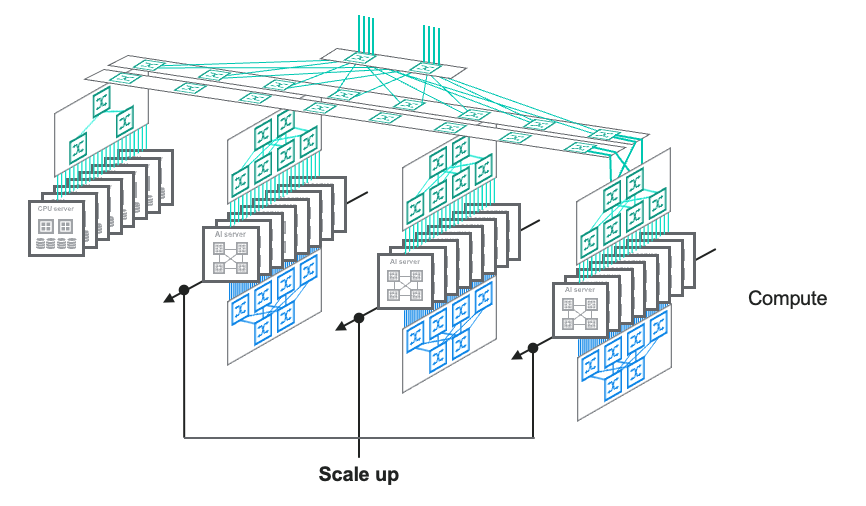
Scale up is the connectivity that couples accelerators into a single compute domain within a rack today and, increasingly, across several. It's the tightest, highest-bandwidth tier, where dozens to hundreds of accelerators act as one.
One connected foundation, from copper inside the rack to optics across rows, plus the switching that ties the domain together:
Switching
Electrical interconnect
Optical interconnect
Memory
Learn More
Learn More
Learn More

Scale up tightly couples accelerators into a single compute domain — within a rack, and increasingly across a few racks. Scale out connects many such domains — row upon row of racks across a floor — into one cluster. Scale across connects separate data centers. Scale up makes many accelerators act as one domain, while scale out ties many domains into a cluster.
Marvell builds the silicon for both tiers. For scale up, that spans switching—a portfolio across PCIe, UALink, ESUN, and NVLink-compatible protocols, with the Teralynx T100 as today’s Ethernet bridge—and interconnect, from copper and co-packaged copper (CPC) inside the rack to Photonic Fabric optics across racks. The same Teralynx switch silicon also serves scale-out fabrics, so a single vendor can supply both tiers rather than lining up a separate chip vendor behind each protocol.
Co-packaged copper (CPC) extends copper reach one step further inside the rack by driving signals with Marvell SerDes straight from the package to the cable, skipping the loss of traditional board routing for the highest signal integrity and lowest power per bit. It’s the last copper packaging step before a link has to go optical, and it’s built into the Teralynx T100 as a packaging option.
Scale up is the connectivity that couples accelerators into a single compute domain. It’s within a rack today and increasingly across several racks. It's the tightest, highest-bandwidth, lowest-latency tier, where dozens to hundreds of accelerators are connected so directly they appear to AI software as one logical XPU.DSP chips convert electrical data into optical signals, correct distortions, and optimize transmission quality—enabling faster, low-error data transfer across fiber networks.
Scale up tightly couples accelerators into a single compute domain—within a rack and increasingly across a few racks. Scale out connects many such domains—row upon row of racks across a floor—into one cluster. Scale across connects separate data centers. Scale up makes many accelerators act as one domain, while scale out ties many domains into a cluster.
Several, and the industry hasn't settled on one. PCIe is in limited use today. UALink and ESUN (Ethernet scale-up networking) are open standards built specifically for scale up, with switches maturing. Ethernet serves as the bridge until those are ready. NVLink is a widely used option, supported by Marvell through NVLink Fusion. Marvell builds switch silicon across all of them.
Inside the rack, over a meter or two, copper is the most reliable, lowest-power, lowest-cost way to connect accelerators, driven by Marvell SerDes. Co-packaged copper (CPC) extends copper one step further by driving the signal straight from the package to the cable. Only when a scale-up domain grows past a single rack do the longer links need to go optical.
Yes. The tightest, densest links in a scale-up domain are where co-packaged optics (CPO) pay off, placing a photonic chiplet beside the compute silicon for maximum density and power efficiency. Scale up is the natural home for CPO, while pluggable optical modules lead the scale-out fabric.
As models grow, memory capacity and bandwidth become as much a constraint as compute. Marvell Structera X devices expands CXL memory at server level, and Marvell Photonic Fabric memory modules extend a shared-memory tier optically across multiple racks up to 50 meters, with up to 32TB of warm KV cache, so memory can scale more independently of compute.
The full scale-up connectivity stack: copper cabling and co-packaged copper (CPC) inside the rack, driven by Marvell SerDes from the scale-in layer; Photonic Fabric technology and a range of photonics approaches for optical links across racks; a scale-up switch portfolio spanning PCIe, UALink, ESUN, and NVLink-compatible protocols, with the Teralynx T100 switch as today's Ethernet bridge; and Structera X memory expanders and Photonic Fabric memory for rack- and domain-level memory scaling..
We believe better partnerships help to build better technologies. Let’s connect and see what we can design together!
We will be in touch with you soon!


